
Claude vs Grok: I ran both on a question Google gets wrong
Claude vs Grok, both run on the same two prompts. Both got the hard question right, but Grok opened 3 vendor pages while Claude cited 9 third-party posts.
Contents
Same answer, different evidence: the verdict up front
Google’s own AI Overview for Claude vs Grok says Claude wins reasoning and writing while Grok wins speed and real-time data. I put both through the same two prompts on the same afternoon, and that framing did not survive contact.
| Claude | Grok | |
|---|---|---|
| Best for | Prose, long reasoning, anything with a byline | Checkable facts about a named company |
| Best free tier | Assistant only, no model choice | Five-mode picker, including a reasoning mode |
| Best overall value | Pro at $20, or $17 billed annually | Free, if the free tier covers you |
Both got a hard factual question right. Both obeyed all four rules on a constrained writing task. The thing that actually separated them was not accuracy and not speed. It was which sources each one decided to trust.
How I tested this, and what that does not prove
Two prompts, run once each, in live logged-in sessions on 27 August 2026. Every screenshot below is from those runs.
One asymmetry matters and I am not going to bury it. Grok ran on a free account in its default mode, which is Fast on Grok 4.5. Claude ran on a paid Max account on Opus 5 at high effort. That is not a like-for-like capability test, and anyone telling you a free tier and a $100-a-month plan are a fair fight is selling something.
What it is like-for-like on is the question most people actually have: what does each one give me when I open it and type, without changing any settings. That is the comparison below.
The other limit is sample size. Two prompts, two tools, four answers. Run once. This is an anecdote with receipts, not a benchmark, and I would not extrapolate from it to a general claim about which model is smarter. What it can do is show you two specific behaviours in enough detail to be useful.
I also did not test a paid Grok plan. In August that meant SuperGrok, whose upgrade screen I captured; since October it means The X Subscription, whose prices below come from xAI’s own pricing page. I generated no paid Grok output and will not characterise any.
Claude vs Grok, side by side on twelve axes
| Axis | Claude | Grok |
|---|---|---|
| Free tier | Yes, assistant only | Yes, with a five-mode picker |
| Free model choice | None | Fast, Build, Auto, Expert, Heavy |
| Entry paid plan | Pro, $20/mo | Plus, $8/mo |
| Annual discount on entry plan | Yes, $17/mo equivalent | Yes, $80/yr |
| Top consumer tier | Ultra, $200/mo (Max $100) | Ultra, $200/mo |
| Annual billing at the top | No, Max is monthly only | Yes |
| Age confirmation to start | No | Yes |
| Searched the web unprompted | Yes | Yes |
| Opened the vendor’s own pages | No | Yes |
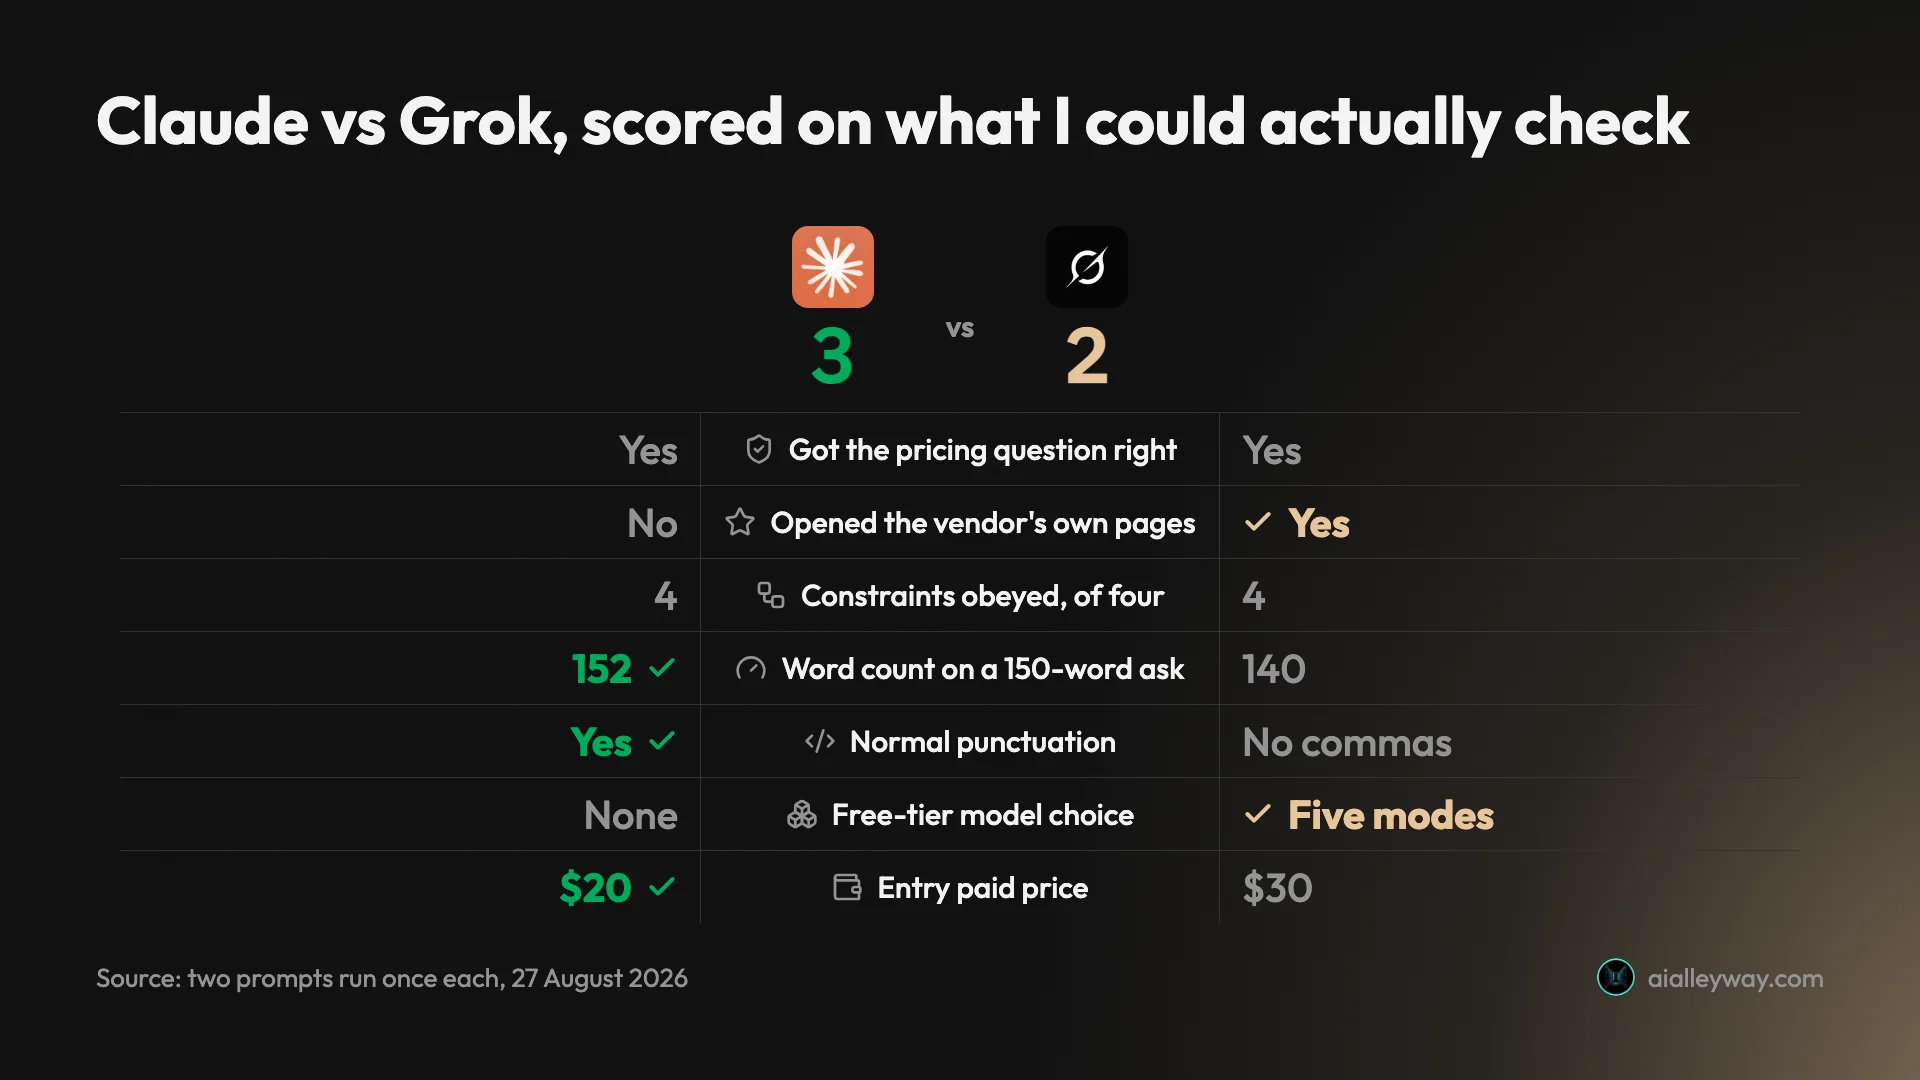
| Sources cited on the test question | 9 results, mostly third-party | 3 pages opened, 30 sources |
| Constraints obeyed, out of four | 4 | 4 |
| Word-count accuracy on a 150-word ask | 152 | 140 |
Two rows in that table carry most of the argument: “opened the vendor’s own pages” and “sources cited”. The rest is context.
Grok: five free modes and an age gate
The free tier is more generous than I expected, and the reputation for Grok being the loose, unserious one does not match what the account actually offers.
Opening the model picker on a free account gives five entries: Fast on Grok 4.5, Build on Grok 4.6 marked beta, Auto which chooses between Fast and Expert, Expert which thinks harder on Grok 4.5, and Heavy, described as a team of experts. Compare that to ChatGPT’s free tier, which our ChatGPT review documents as having no picker at all, and to Gemini’s four selectable modes covered in our ChatGPT vs Gemini comparison.
A caveat I want to be precise about. The presence of a mode in the picker is not proof of unlimited use of it. Grok’s own upgrade screen lists “smarter answers in Expert mode” as a paid benefit, which implies the free version of Expert is metered or capped in some way the interface does not spell out. Read those five entries as access, not as an allowance.
Two rough edges in August. Grok made me confirm my birth year before it would answer anything at all, which is a gate neither Claude nor ChatGPT imposed on me. And grok.com/pricing was a 404, with the plan prices living behind the in-app upgrade screen. That second one is fixed: since October, x.ai/pricing is a public page you can send a colleague.
Claude: weaker at the free end, stronger above it
Claude’s free tier is the weaker of the two on paper. There is no model picker, and the free assistant is the product rather than a doorway to a range of them.
Where Claude earns its keep is above that line, and our Claude review rates it 4.4 on the strength of daily use on a paid plan. The thing it is genuinely best at in this category is prose that holds a shape over length — style guides with prohibitions in them, long drafts where the last third has to be as disciplined as the first.
The structural quirk in Claude’s pricing is at the top rather than the bottom. Pro at $20 discounts to $17 if you pay annually, but Max at $100 and Ultra at $200 show no annual price on the pricing page. Our Claude Max plan guide works through what those multipliers actually buy.
Its weakness against Grok on the test below is not intelligence. It is that when Claude searched, it did not go to the source.
Claude vs Grok pricing: which one costs less?
When I first wrote this, Grok had one consumer paid plan and Claude had three rungs. That changed on 12 October 2026, when xAI folded Grok into The X Subscription, one plan covering Grok, Cursor and X. Grok now has the longer ladder.
The X Subscription runs Free, Plus at $8, Premium at $30, Super at $100 and Ultra at $200 a month, all from xAI’s pricing page. Plus includes Grok Chat, Voice, Imagine and Build. Premium gives four times Plus’s usage and, in xAI’s words, “the benefits of SuperGrok”. Super and Ultra give 15 and 50 times. One usage pool is shared between Grok and Cursor and refreshes weekly.
Every rung can be paid yearly: $80, $300, $1,000 or $2,000 a year, per Cursor’s plan documentation. Premium at $300 a year against $360 paid monthly is the same 17 percent saving SuperGrok offered.
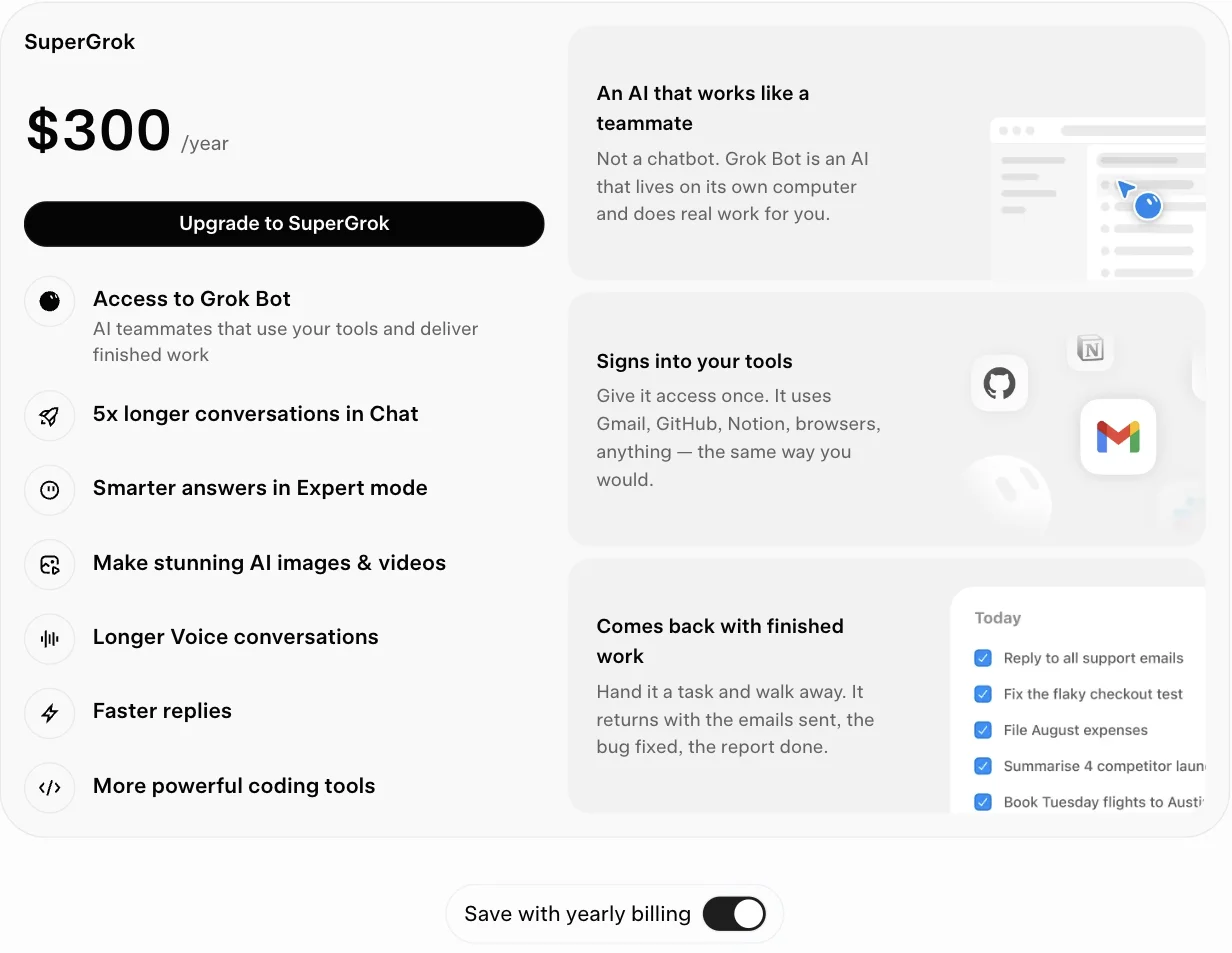
That screenshot is the August upgrade screen, when SuperGrok was $30 a month, or $300 a year. SuperGrok still exists for people who already pay for it, since xAI says nothing changes for existing subscribers, but new customers buy The X Subscription.
Claude Pro is $20 a month, or $17 a month billed annually, which is a 15 percent discount. Claude Max is $100 a month and Ultra is $200, with no annual price listed. Those are from Claude’s pricing page.
Read those together and the picture is not “one is cheaper”. At the very bottom Grok is, by a wide margin: Plus at $8 against Claude Pro at $20. But xAI itself recommends Plus for social creators with limited AI use and steers new AI users to Premium at $30, so for someone who will lean on the assistant daily, Claude Pro is still the cheaper door by a third. Above that the two ladders now mirror each other, $100 and $200 on both sides, which means Grok has acquired its own version of the $100 question our ChatGPT Plus vs Pro guide had to untangle.
One difference to weigh: Grok’s pool is shared with Cursor. If you also code in Cursor, the same allowance pays for both, which is good value if you use both and a quiet drain on your chat budget if you do not notice it.
Grok also wins a structural point: every rung can be paid yearly, while Claude’s Max tiers cannot be paid annually at all. The discount exists only at the bottom of Claude’s ladder and on every rung of Grok’s.
One more observation, offered as an observation rather than a conclusion. In August, Grok showed me its prices in US dollars. ChatGPT’s pricing page, opened from the same machine on the same day, geo-locked to my local currency and never showed me a dollar figure at all. I am not going to convert anything or claim one approach is better. It is simply worth knowing that the price you see depends on the vendor’s choice as much as on the plan.
The test: both got the hard question right
Here is the question I set them, and why it is a good one:
How much does ChatGPT Pro cost, and how many Pro tiers are there?
This is a trap for stale sources. When I ran the test on 27 August 2026, OpenAI sold Pro at two prices, $100 and $200, while a great deal of the writing on page one of Google still described Pro as a single $200 plan. OpenAI has since added a third, at $500, so the right answer today is three. OpenAI’s help-centre article on Pro tiers lists all three, and our ChatGPT Plus vs Pro guide covers what separates them.
Grok answered correctly, in 11 seconds.
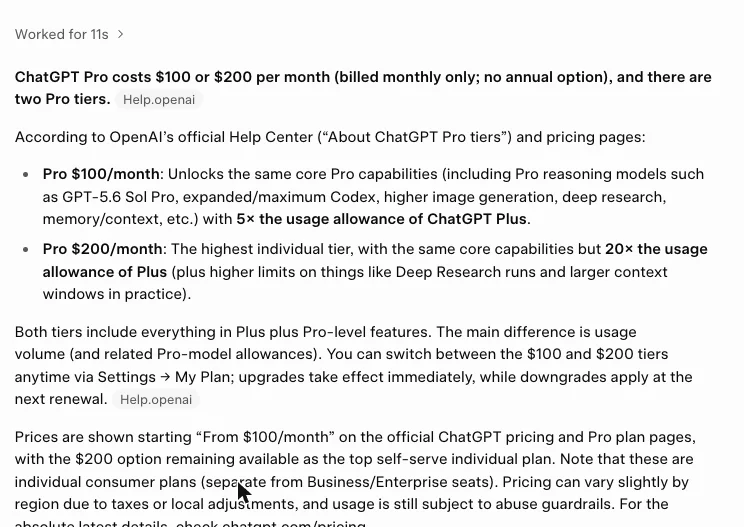
It ran three searches and opened three pages: OpenAI’s help-centre article on Pro tiers, chatgpt.com/pricing, and the Pro plan page. Then it gave both prices, both multipliers, the monthly-only billing constraint, and the detail that the pricing page presents Pro as “From $100/month”. Every one of those matches what I verified at the source myself.
Claude also answered correctly.
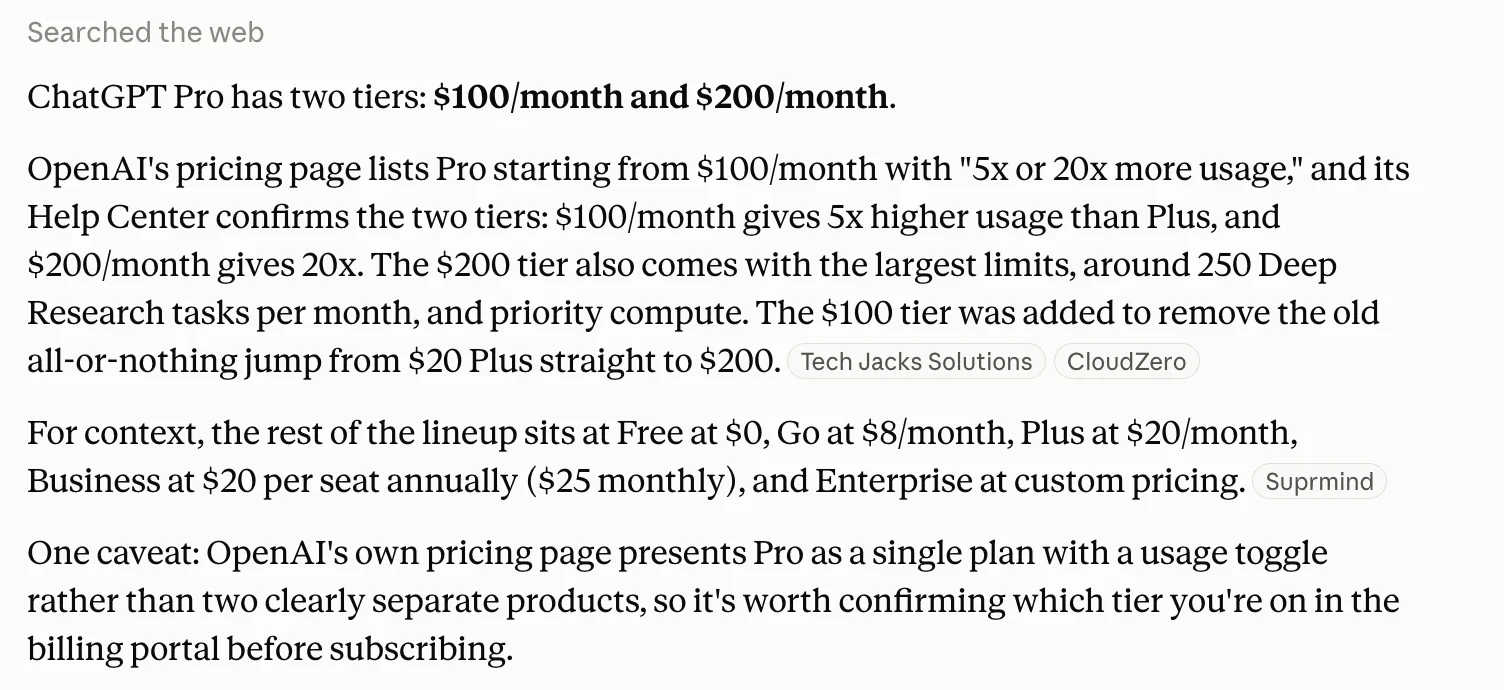
Same headline figures, same multipliers, and a sharp closing caveat that OpenAI’s pricing page “presents Pro as a single plan with a usage toggle rather than two clearly separate products” — which is exactly the confusion I ran into first-hand.
So on accuracy: a tie. Both beat page one of Google.
The difference is underneath. Grok read OpenAI’s pages. Claude cited nine results, most of them third-party pricing roundups and comparison articles, with the vendor’s page among them rather than leading. Both chains reached the same place, but one of them is checkable in a single click and the other depends on how recently a handful of aggregators updated their posts.
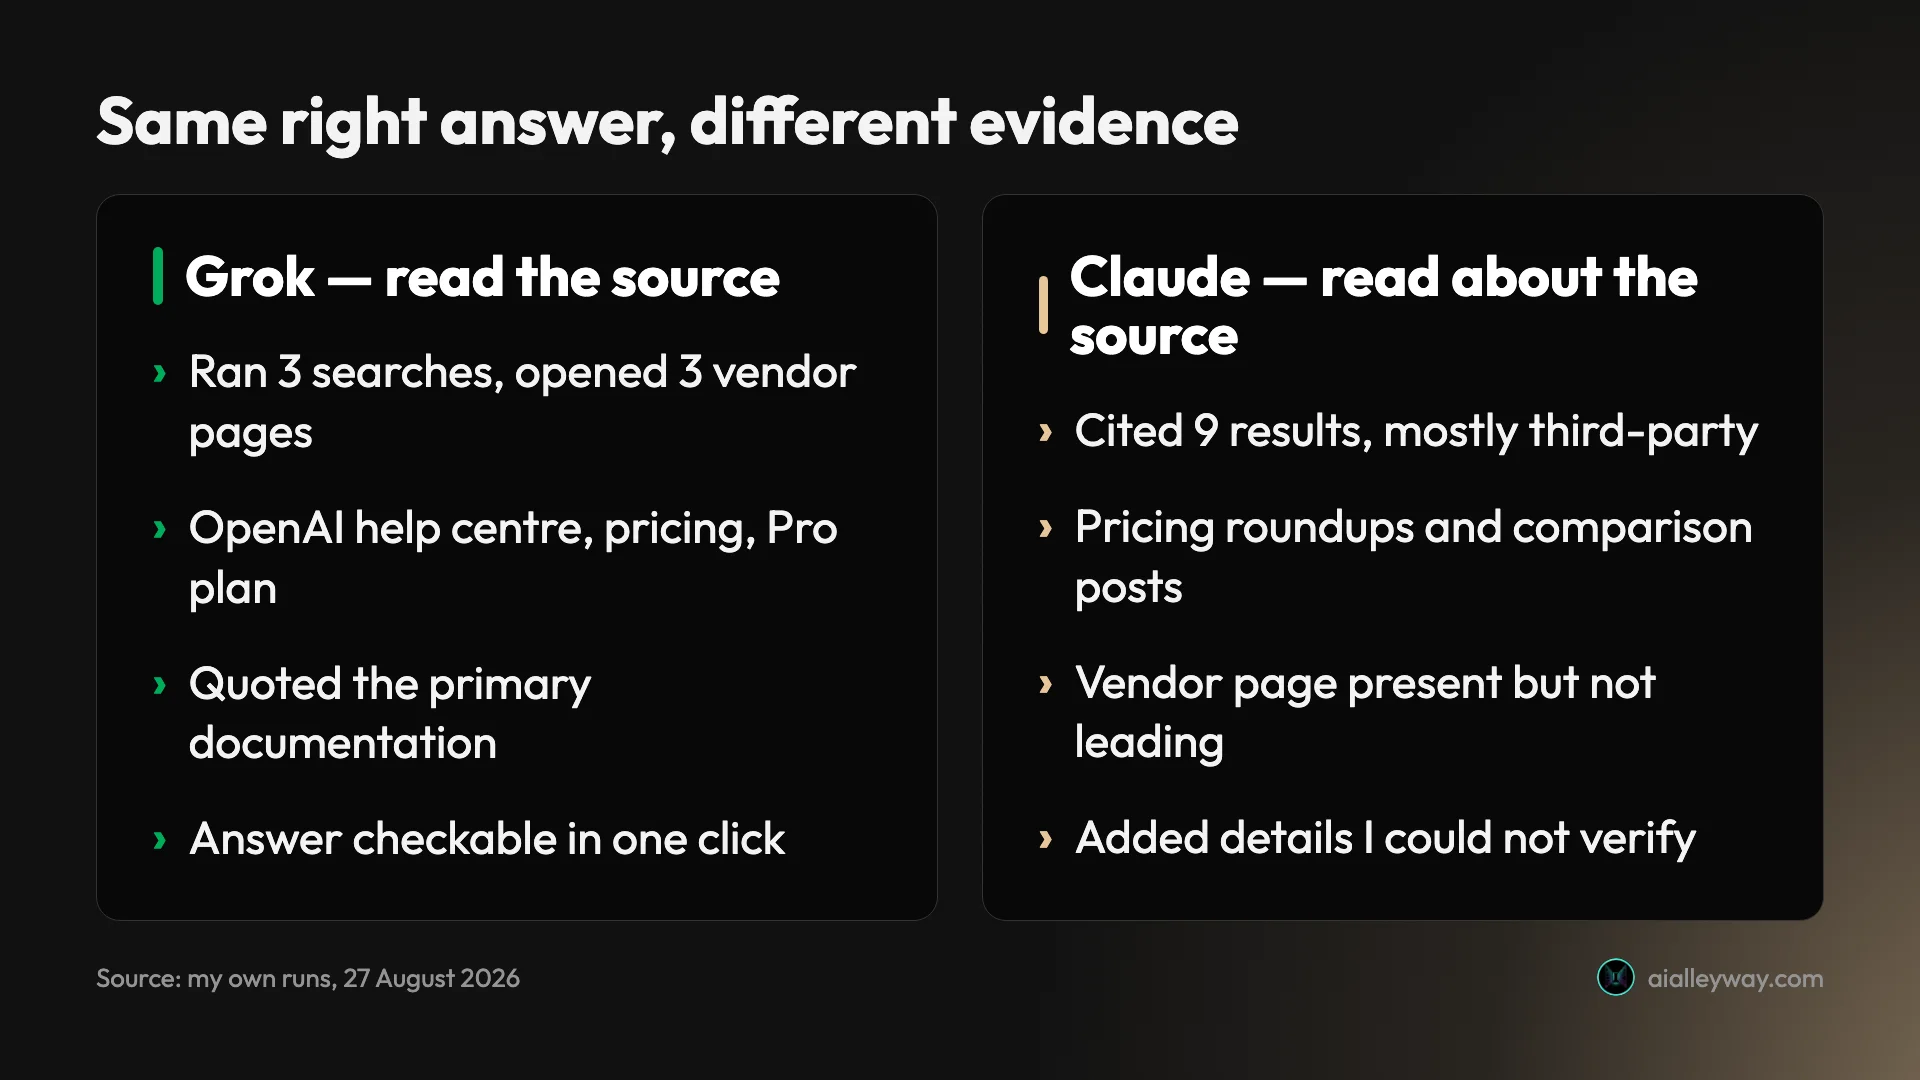
That has a practical consequence. Claude’s answer also included details I could not verify at OpenAI, among them a specific monthly count of deep research tasks on the top tier. I am not saying those are wrong; I have no way to know, and they may well be accurate. I am saying they came from articles about OpenAI rather than from OpenAI, and the answer gives you no way to tell which parts are which.
What the wait buys, and why I am not calling it a speed test
The speed gap everyone talks about barely showed up.
Grok reported working for 11 seconds on the pricing question. Claude thought for 14 seconds on the writing task. Read those as two samples rather than a race. They come from different prompts, and I did not record the matching times for Grok on the writing task or Claude on the pricing one, so this is not a controlled speed test.
What it does show is that neither made me wait in a way that would change how I work, which is the only speed question most people actually have.
Where the two genuinely diverge is in what happens during those seconds. Grok’s trace is a browsing trace: searches run, pages opened, a line saying it was confirming pricing details. You can see the work and audit it. Claude’s is a thinking trace followed by a citation list, which tells you it reasoned but not where the reasoning touched ground.
For a factual lookup, the browsing trace is more useful, because the thing you want to check is the sources. For a writing task, the thinking time is the thing you are paying for, and there is nothing to audit.
| Around the chat box | Claude | Grok |
|---|---|---|
| Saved workspaces | Projects | Projects |
| Generated outputs | Artifacts | Imagine |
| Runs on a schedule | Scheduled | Automations |
| Reaches your other tools | Not a sidebar entry | Skills and Connectors |
| Second working mode | Cowork | Build |
The wider workflow difference is what each product wraps around the chat box, and the two have made visibly different bets. Grok’s sidebar offers Imagine, Automations, Skills and Connectors and Projects, with a Build mode in the model picker. Claude’s offers Projects, Artifacts, Scheduled and Customize, with a Cowork mode alongside Chat.
Reaching other tools is a named sidebar entry on Grok and not on Claude, which is a statement about the menus rather than about what either can do. Grok is reaching toward acting inside other tools, and its paid pitch is an agent that signs into your Gmail and GitHub and comes back with the work done. Claude’s surfaces lean toward producing and organising artefacts you then use yourself.
Neither of those bets is settled, and I did not test either, so treat that paragraph as a description of the menus rather than a verdict on what is behind them.
One small thing the transcripts do differently. After answering, Grok offered three follow-up prompts, including one that read “Rewrite text to strictly follow all constraints” — an odd suggestion given it had followed all of them, and a hint that the interface guesses at follow-ups without checking the answer above it. Claude offered none, leaving the next move to me.
The writing test, and one strange artefact
Second prompt, four rules, all objectively checkable:
Write 150 words on why a small team might pick a cheaper AI assistant. Rules: no bullet points, no em dashes, no sentence starting with “But”, and the last word must be “budget”.
I expected this to be where Claude pulled clear, since instruction-following under constraint is the axis its reputation rests on. It did not go that way.
| Claude | Grok | |
|---|---|---|
| No bullet points | Pass | Pass |
| No em dashes | Pass | Pass |
| No sentence starting with “But” | Pass | Pass |
| Last word is “budget” | Pass | Pass |
| Words delivered against 150 | 152 | 140 |
| Commas used | 7 | 0 |
Both scored four out of four. Neither broke a stated rule.
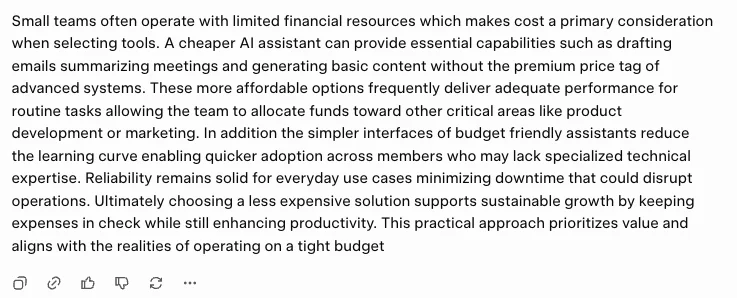
Grok’s came in at 140 words against the 150 asked for, and landed the mandatory final word cleanly. The odd part is the punctuation: 140 words containing not one comma. Nothing in the prompt banned commas. The likeliest explanation is that it generalised the em-dash prohibition into a broader avoidance of punctuation, which is a reasonable instinct applied too widely, and the prose reads breathlessly as a result.
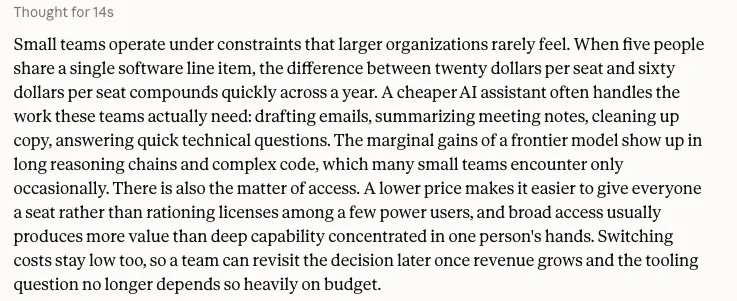
Claude hit 152 words, two over, and wrote normally punctuated prose. It was also the more concrete of the two, inventing a five-person team and a per-seat price gap to argue with where Grok stayed at the level of “limited financial resources”. Those figures are illustrative colour the prompt invited, not researched numbers, and neither tool was asked for real ones.
That concreteness is the real difference, and it is a quality judgement rather than a rule check, so weigh it accordingly. On the part that can be scored objectively, this was a tie.
Grok is the right call if…
You check facts about specific companies. This is the strongest case, and it is the one my test actually supports. If your questions are of the form “what does this product cost now” or “what did this company announce”, the tool that opens the company’s own pages is the one you want.
You want a capable free tier with real model choice. Five modes including a reasoning mode, at no cost, is a better free offer than several rivals make.
You want the cheapest paid entry, or yearly billing at the top. Plus at $8 is the lowest paid price on either ladder, and Super and Ultra can be paid yearly where Claude Max cannot. If you also code in Cursor, one subscription covers both.
Skip it if your work is prose that carries your name. Nothing in my test suggested Grok is bad at writing, but the comma artefact is the kind of quiet oddity you would have to edit out every time.
Claude is the right call if…
Your output is prose people read. This remains the clearest single-axis result across every assistant this site has tested, and the constrained-writing task did nothing to weaken it even though the rule-following was a tie.
You want the cheaper door for daily use. $20 against Grok Premium’s $30, or $17 annually, and it buys the model most people rate highest for written work. Grok Plus is cheaper still at $8, but xAI pitches it at light users.
You need long reasoning to hold together. The gap shows up in the last third of a long piece rather than the first paragraph, which is exactly where a two-prompt test like mine cannot see it.
Skip it if the thing you actually need is current facts about a named company, and you are not going to check the sources yourself. On that job Claude reached the right answer through weaker evidence, and the next time the aggregators are stale it may not.
Final word
The received wisdom on this comparison is that Claude is the smart one and Grok is the fast one. My session did not support either half of that cleanly. Both answered a genuinely hard factual question correctly when most of the internet still answers it wrong, both followed every constraint in a writing test designed to catch sloppiness, and neither response made me wait in a way I noticed.
What did separate them was sourcing discipline. Grok went to the vendor’s own documentation and quoted it. Claude went to articles about the vendor and reached the same answer with a weaker chain behind it. For anyone using an assistant to check facts rather than to generate prose, that is the difference worth choosing on, and it is not the difference the comparison articles are arguing about.
If you want one recommendation for a typical buyer: Claude Pro at $20, because prose quality is what most people actually buy an assistant for and it costs a third less than Grok Premium, the plan xAI recommends to new AI users. Keep a free Grok account open in another tab for the moments when you need to know what something costs today, and check what it opened before you believe it.
For the wider field at the same price, our ChatGPT vs Claude comparison covers the two most people are choosing between, and ChatGPT alternatives has the six-tool version.
Frequently asked questions
Is Grok better than Claude?
Neither wins outright, and the honest answer depends on which failure you are more worried about.
I ran both on the same two prompts. On a factual question where most of page one is out of date, both returned the correct answer. On a writing task with four explicit constraints, both obeyed all four. Straight accuracy did not separate them.
What separated them was sourcing. Grok opened the vendor's own help centre and pricing pages and quoted them. Claude leaned on third-party articles about the vendor, the kind of pricing roundup that goes stale within weeks.
Where the primary source is authoritative and the secondary coverage is behind, that gap matters more than model quality.
One caveat that matters for reading any of this: Grok ran on a free account in its default mode and Claude on a paid Max account, so this is not a like-for-like capability test.
So: Grok for checkable facts about a specific company, Claude for reasoning and prose.
How much does Grok cost compared to Claude?
Since 12 October 2026, new Grok customers buy The X Subscription, one plan covering Grok, Cursor and X. It runs Free, Plus at $8, Premium at $30, Super at $100 and Ultra at $200 a month. Claude has a free tier, Pro at $20 a month or $17 billed annually, and Max at $100 or $200 a month.
The cheapest paid door is now Grok's. Plus at $8 includes Grok Chat, Voice, Imagine and Build, though xAI itself recommends Plus for social creators with limited AI use and points new AI users at Premium. Premium at $30 carries what used to be SuperGrok, so a heavy chat user still pays more for Grok than for Claude Pro at $20.
Above that the ladders now line up: Claude Max at $100 or $200 against Grok Super at $100 and Ultra at $200.
The structural difference is billing. Grok's plans can be paid yearly at every rung, $300 a year for Premium against $360 paid monthly. Claude discounts only Pro, and Max is monthly only at any price.
Existing SuperGrok subscribers keep their plan; xAI says nothing changes for them.
Does Grok have a free tier?
Yes, and it is more generous than I expected before I opened it.
A free Grok account gives you a model picker with five entries: Fast on Grok 4.5, Build on Grok 4.6 in beta, Auto which chooses between Fast and Expert, Expert which thinks harder on Grok 4.5, and Heavy described as a team of experts.
That is a wider selection than several rivals hand a non-paying account. ChatGPT's free tier offers no picker at all, which our ChatGPT review documents.
Two caveats from my own session. Grok asked me to confirm my age before it would answer anything, which is a step the others do not impose. And the presence of a mode in the picker is not proof of unlimited use of it, since the upgrade screen advertises smarter answers in Expert mode as a paid benefit. Treat the five entries as access, not as an allowance.
Which is better for writing, Claude or Grok?
Claude, on the evidence of the one constrained writing task I set them, though the margin was narrower than the reputation gap suggests.
I asked both for 150 words with four rules: no bullet points, no em dashes, no sentence beginning with the word But, and a mandatory final word. Both obeyed all four. Neither broke a single stated constraint.
The difference was in what neither was asked. Claude landed on 152 words against the 150 requested. Grok came in at 140. Claude's prose carried concrete detail, inventing a five-person team and a per-seat price gap to argue with, where Grok stayed general. Those numbers are illustrative colour, not researched figures.
The oddest artefact was punctuation. Grok's 140 words contained no commas at all, which reads strangely and suggests it over-applied the em-dash ban to punctuation generally. Nothing in the prompt asked for that.
Is Grok's real-time data actually an advantage?
On the test I ran, yes, and in a more specific way than the usual framing suggests.
The standard claim is that Grok is fresher because it reaches live data from X. What I actually observed was different and more useful: Grok went to the primary source. Asked about ChatGPT Pro pricing, it opened OpenAI's help centre article and OpenAI's pricing page directly, then quoted them.
That mattered because the question was one where the secondary coverage is wrong. OpenAI then sold Pro at two prices, and much of page one of Google still described a single plan; it has since added a third, at $500.
Claude reached the right answer too, but via articles about OpenAI rather than OpenAI's own pages. Same conclusion, weaker chain of evidence.
The lesson generalises: for a checkable fact about a named company, prefer whichever tool reads that company's own documentation.
Can Claude access the internet like Grok?
Yes. Claude searched the web unprompted on the factual question I asked, and cited nine results, so live retrieval is not a Grok exclusive.
The difference I observed was not capability but selection. Claude's nine citations were mostly third-party pricing roundups and comparison articles, with the vendor's own pricing page among them. Grok ran three searches, opened three vendor pages, and reported drawing on thirty sources.
Both reached the correct headline figure. Claude added several details I could not verify from the vendor's pages, including a specific monthly count of deep research tasks, and attributed them to those third-party articles.
That is the practical caution. When an assistant cites an aggregator rather than the source, the answer inherits the aggregator's staleness and its errors, and you cannot tell which parts are affected without checking yourself.
Worth knowing before you weigh this: Grok was on a free account and Claude on a paid Max plan, and each prompt ran once.
Keep reading
Claude AI review: brilliant at words, strange about limits
A Claude AI review from a paying Max account. My $100 Max plan invoiced at $111.11, three usage meters run at once, and overflow is billed at API rates.
Claude Artifacts tested: a working app in 2 minutes, private at first
I built a tip calculator, a five-slide deck and an AI reply tool as Claude artifacts. What saved, what exported, what asked permission, and what Free gets.
Claude Max plan: 5x now covers your week, and 20x is gone
Claude Max is $100 a month for 5x Pro usage every five hours and every week. The $200 tier is now Ultra: no five-hour cap, 10x Pro weekly. Which one to buy.
Claude Projects tested: what it finds, and what it can't read
I built a Claude project with three files and ran six chats. It found one line in a 1.46 MB file, but could not count across it. Setup, limits and plans.